One platform. No handoffs. Better agents, shipped faster.
Build and test in one place, so every change is tested before it ships.
Disconnected tools and no shared standards slow every stage
Agents are built in one tool and tested in another. Testing is manual: people grade transcripts by hand, against criteria each team sets on its own. The tested version and the shipped version live in different tools, and every change has to be re-run somewhere else. The result is slower releases, uneven quality and risky updates.
60% of teams rely on human review, and 32% cite quality as a top barrier to production.
Source: LangChain, State of Agent Engineering, Nov to Dec 2025.One platform means faster updates and better-tested agents
Experts ship changes without waiting on developers
Infrastructure is ready on day one. Your domain experts build and train agents, run evaluations, pick the version they like and push it to production. Developers focus on the rest of the app.
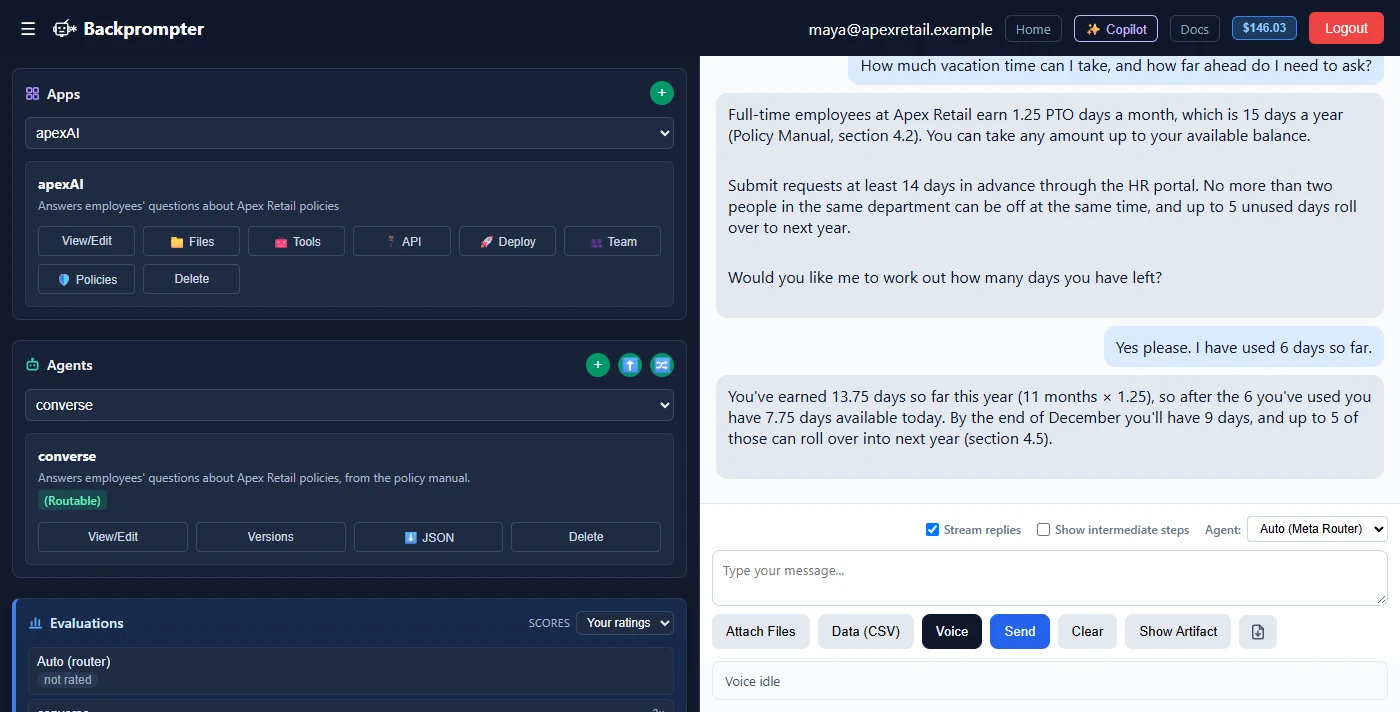
Testing happens where you build
Simulated users and evaluator agents you design test every agent inside the platform, common cases first, then edge cases. Problems surface while you build, not after users find them. No separate evaluation tool, no handoffs.
Test and optimizeEvery step of building, launching and running an agent, in one place
Build
Domain experts build and train agents in plain language, with multi-agent routing, RAG, web search, tools and voice, on any major model. No backend to build.
Build Center02 · TESTTest and optimize
Test against company and app rules with live and simulated users. Evaluator agents you design score each run, batch evaluations check quality, latency and grounding across many conversations at once, and suggested prompt fixes help you improve it.
Test and optimize 03 · DEPLOYDeploy
Call your agent from your app through the API and SDKs, or from Claude Code, Codex, Cursor and other agents over MCP. Or publish it as a hosted chat, website embed or Slack app, in our cloud or air-gapped.
Deploy and earn 04 · MAINTAINMaintain
Domain experts update and ship changes, no developer needed, and re-test every change. No conversation logging by default.
Deploy and earn 05 · EARNEarn
Connect your own Stripe account and charge end users directly.
Deploy and earnEvery agent meets your policies and behaves as designed, before it ships
Backprompter tests every agent against standards set at three levels.
Company rules, set by IT
Policies every agent built on Backprompter must pass, including agents built by teams outside IT. Set once, applied everywhere, and teams can add rules but not remove them.
Solutions: Enterprise SoonApp-specific rules, set by the domain expert or developer
How this agent should act and what good looks like, scored by evaluator agents you design.
Test and optimizeStress testing, run by Backprompter's evaluation pipeline
Simulated users put the agent through everyday requests and edge cases, and evaluator agents score every conversation.
Test and optimizeOne platform instead of a builder plus an evaluation tool
App builders are built for screens and code, not for how an agent behaves in conversation. Evaluation tools sit apart from where agents are built and deployed, often as a separate subscription. Agent builders rely on manual spot checks. Building it yourself means maintaining a test harness and a backend. Backprompter brings building, testing, optimization and deployment into one place, with no separate evaluation tool to buy and connect.
No agent too big or too small
From a simple FAQ assistant to a multi-agent workflow held to company-wide rules, every agent goes through the same build, test and ship cycle.